From recording to export.
Watch an actual import, transcript review, source-linked note and export. Inspect the input and outputs below.
Watch the workflow.
16.4-second synthetic recording · Whisper small · CPU/int8. Captured October 28, 2026.
Walkthrough in text
- Import the original garden-planning WAV into VoxNotch.
- Process it with the local Whisper small model. Four timed transcript segments appear beside the source audio.
- Write an action note: buy compost and label each row. Its 0:12 marker seeks to that point in the source recording.
- Export the transcript as Markdown and open the downloaded file outside VoxNotch. JSON, SRT, and separate note exports are also available below.
Listen to the input
16.4 seconds of original synthetic speech created with eSpeak NG. This is input to transcription; it does not demonstrate VoxNotch voice generation.
Inspect the files
The source stays within reach.
Review the transcript
Compare the generated text with the input audio. This example is a short, clear synthetic recording; it does not establish accuracy for meetings, accents, noisy audio, or multiple speakers.
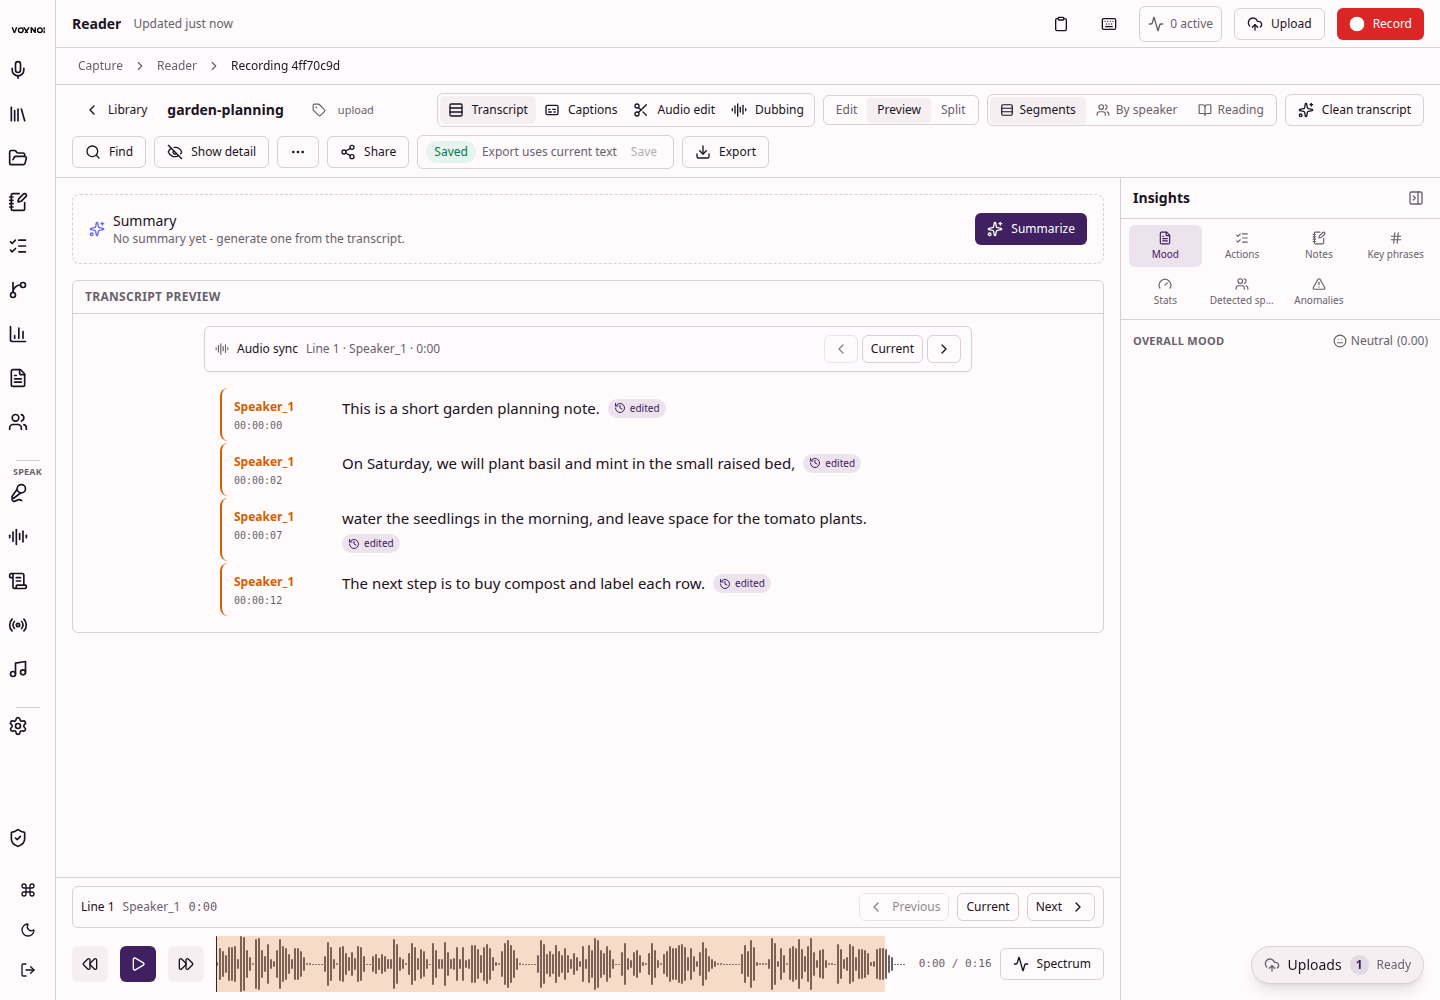
Return to the source moment
The manually written action note links to 12.44 seconds. Clicking its displayed 0:12 marker was checked against the source audio playhead.
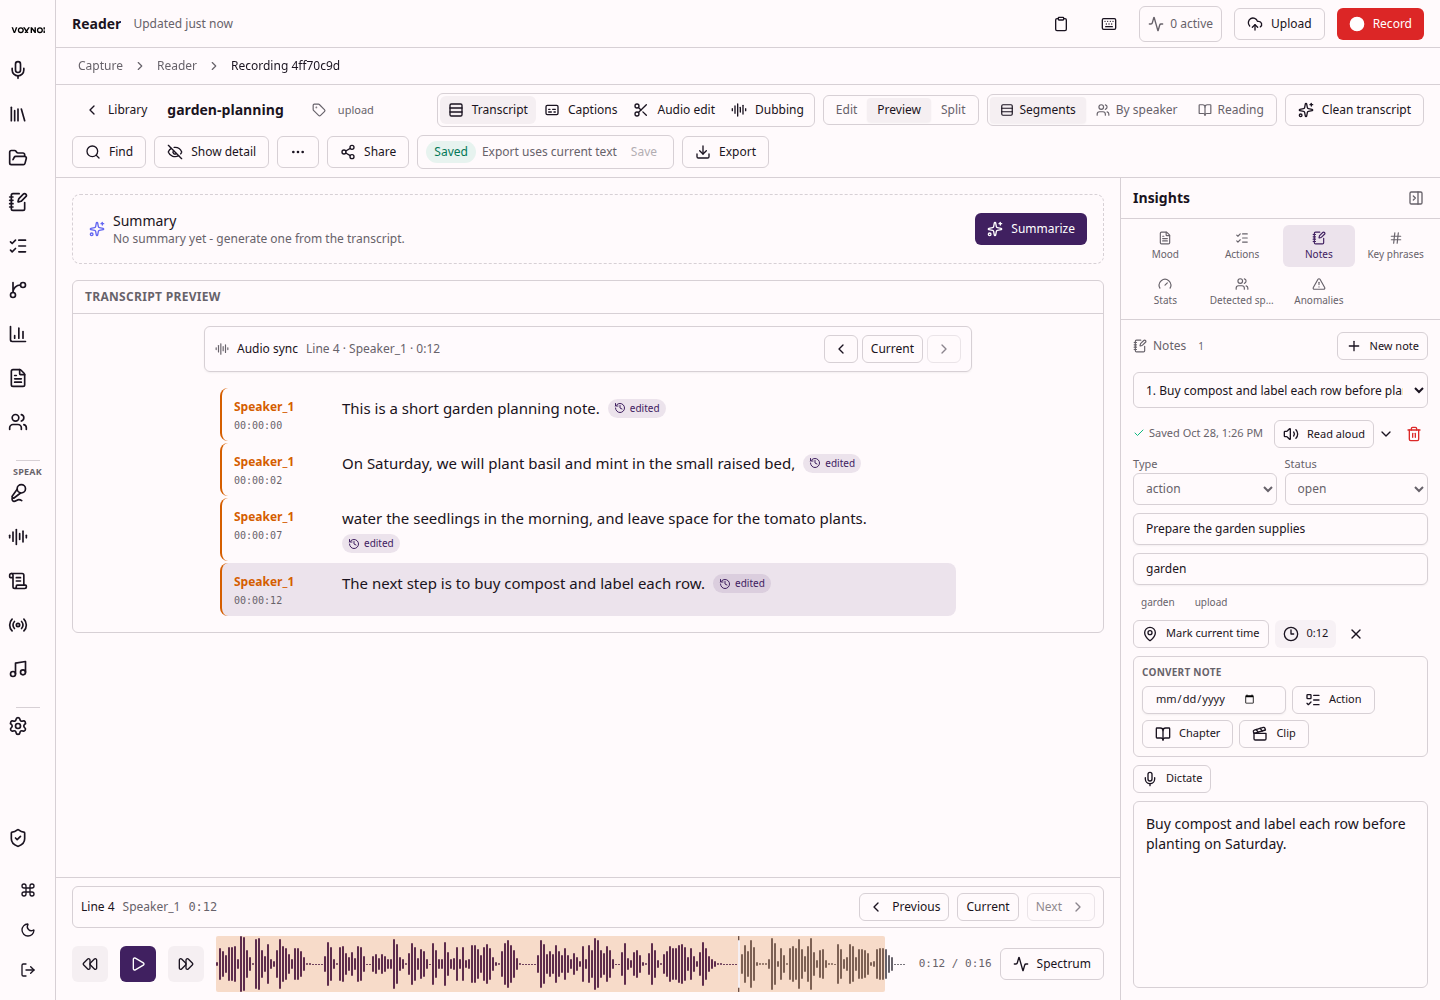
What this example establishes
This run demonstrates file import, real CPU speech recognition, timed transcript review, source-linked notes, and exports from one isolated instance. Model files were downloaded beforehand; transcription used the local model cache.
The evaluation used temporary files, an in-memory store, and an inline job queue. It does not demonstrate persistent storage, a separate worker deployment, production security, or a performance benchmark. The input voice was created with eSpeak NG 1.52.0; VoxNotch speech synthesis was not exercised.
Evaluate your own workflow.
Request beta access with the recording type and output you need. Start with a short, non-sensitive sample after agreeing the evaluation terms.