Audiobook and narration
Turn long text into narrated audio without handing the workflow to a hosted studio.
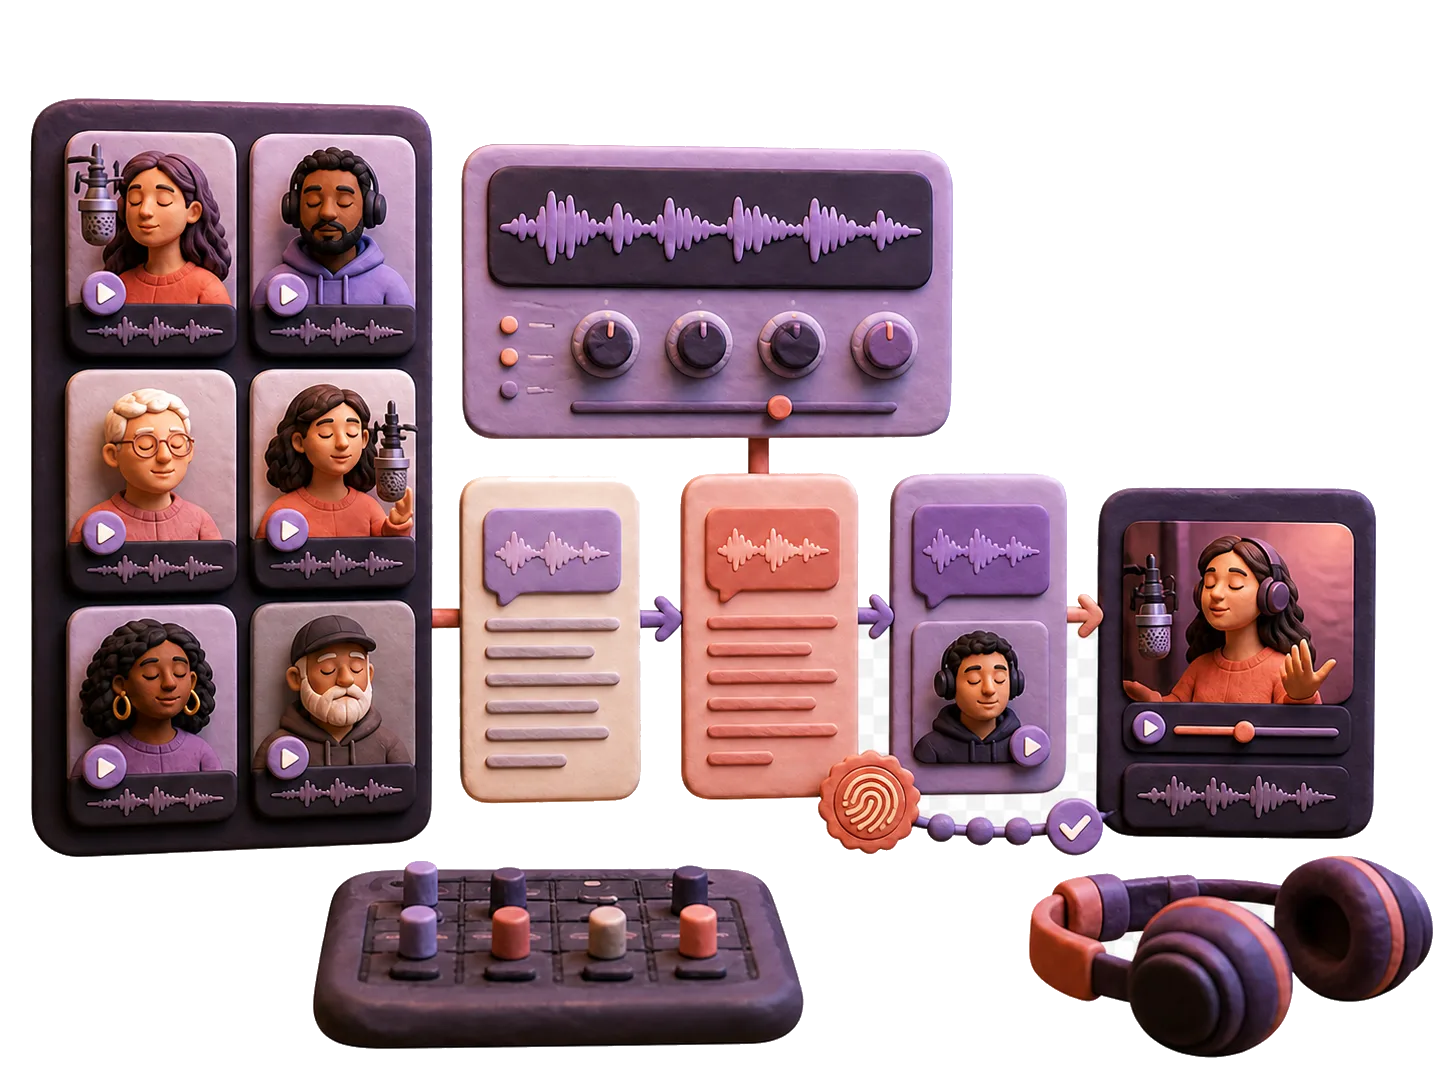
VoxNotch treats narration as a production run: prepare text, choose a local voice, synthesize in batches, review the output, and package chapters from your own instance.
Voice library and narration-ready voice choices.
Workflow
A chapter is a job, not a one-shot text box.
Prepare
Split the manuscript into sections that can be reviewed, retried, and exported without losing the shape of the book.
Choose voice
Use the voice library and voice studio to keep narrator choices explicit instead of burying them in a provider preset.
Voice library with saved voices and usage context. Synthesize
Run batch TTS locally when the engine is available, or route through a configured provider when you intentionally accept that egress.
Review
Keep generated audio as assets, inspect failures, and rerun the sections that need another pass rather than restarting the whole project.
Quality
The quality story is control, not magic.
High-quality narration depends on the voice model, segmentation, pronunciation, room tone, and review loop. VoxNotch gives you the workflow surface to manage those parts deliberately.
Local TTS requires the optional engine and hardware to run it. Provider-backed voices can sound better, but they cross a network boundary you configure on purpose.
Start with one chapter.
Use one short chapter to prove voice choice, pacing, artifact management, and export before committing a whole manuscript.